
Batch processing and stream processing solve different customer-data problems. Batch pipelines process a defined collection of data on a schedule and are well suited to building complete, durable profiles from broad history. Streaming pipelines process new events as they arrive and are well suited to time-sensitive signals and actions.
A useful real-time experience often needs both. The latest browse, purchase, booking, or cancellation becomes more meaningful when evaluated with identity, loyalty, preferences, consent, and purchase history. The architecture must combine that context without promising that every source, profile field, audience, and destination updates at the same speed.
Key Takeaways
Batch processing supports complete and durable customer profiles across larger datasets and longer timeframes.
Streaming makes newly arrived events available for use cases that cannot wait for the next scheduled batch.
Real-time is an end-to-end requirement that includes source delivery, processing, identity, lookup, decisioning, destination, and measurement latency.
Teams should define acceptable freshness for each use case and test the exact path rather than treating real-time as one universal service level.

What is batch customer data processing?
Batch processing works on data that has accumulated by a cutoff point or within a scheduled window. A batch job can standardize fields, resolve identity across many sources, recompute customer attributes, apply governance rules, and publish profiles or audiences for downstream use.
Batch is a strong fit when completeness, reconciliation, reproducibility, or cost-efficient processing matters more than immediate response. Examples include rebuilding a customer 360, calculating historical lifetime value, producing regulatory extracts, and refreshing large analytical datasets.
What is real-time customer data processing?
Stream processing evaluates events as they arrive or within a short, ongoing window. It can make recent behavior available for a lookup, rule, audience change, or downstream action without waiting for the next full batch.
Examples include suppressing a promotion after a purchase, responding to a cart or booking abandonment, showing recent transactions to a service agent, or using a current loyalty event in a digital experience. The required latency may be seconds for one use case and minutes for another.
Why neither layer is sufficient for every use case
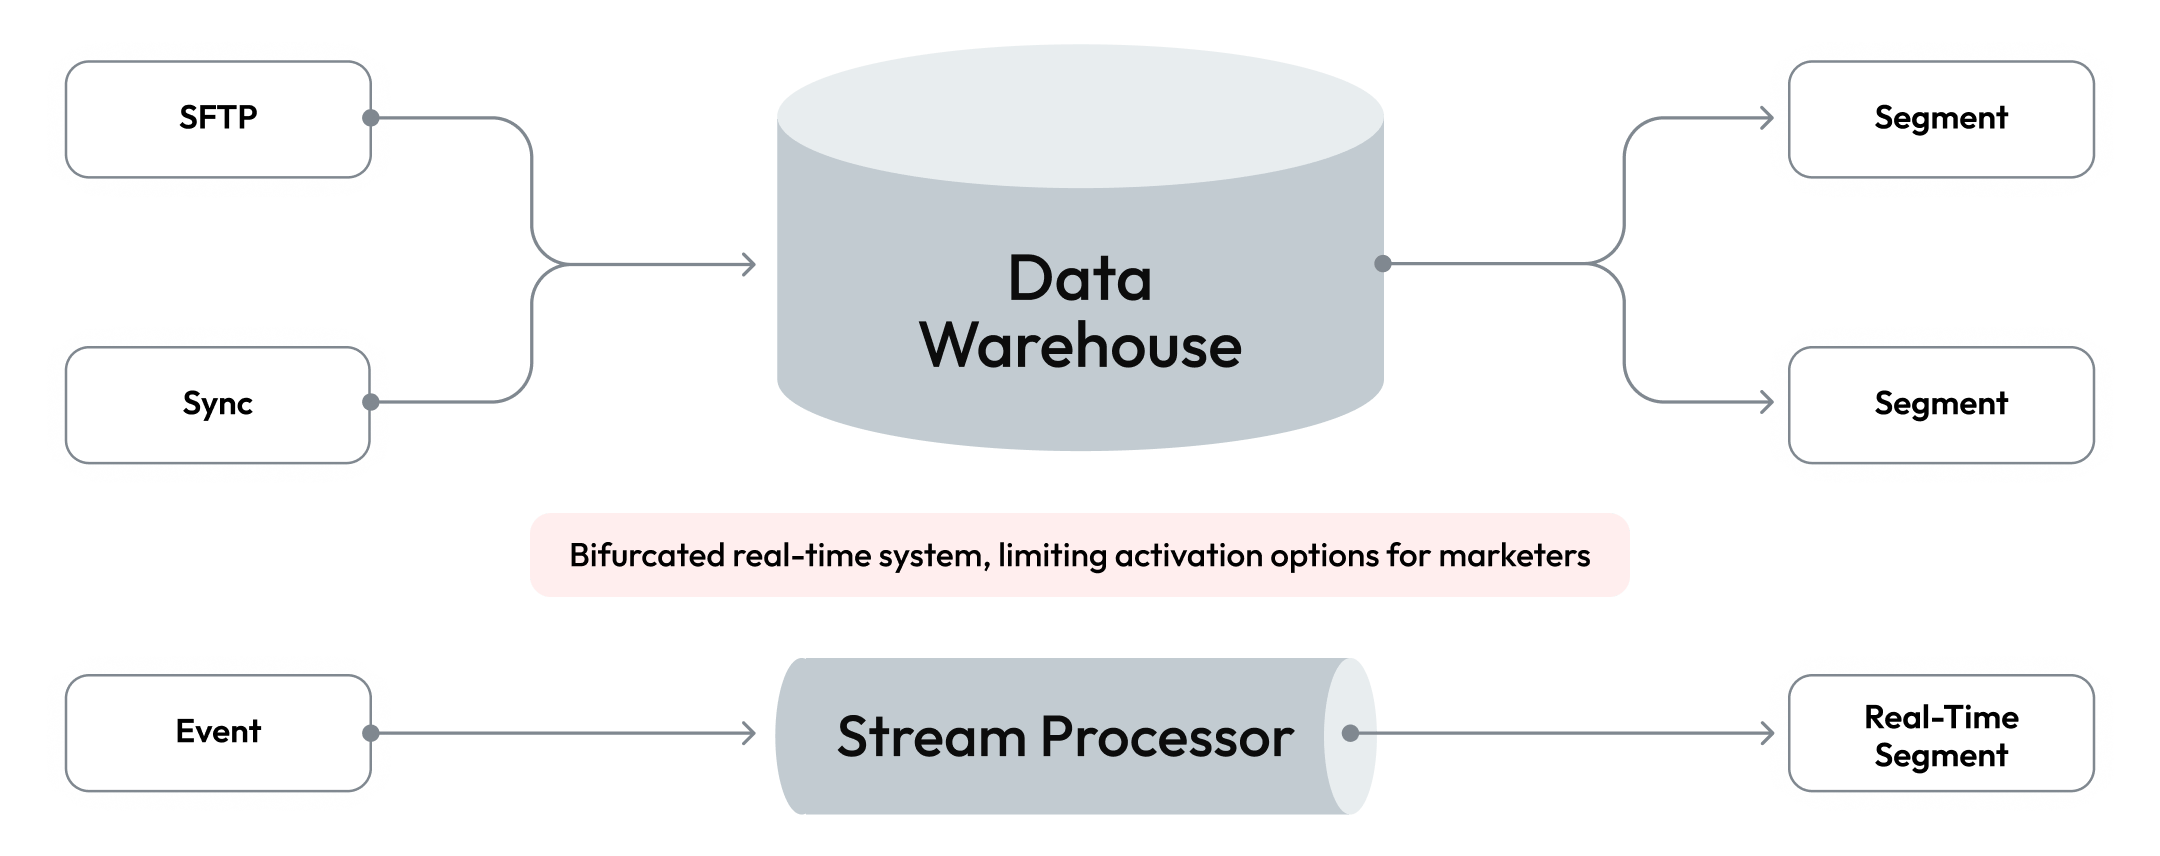
A scheduled profile may contain complete purchase and loyalty history but miss an event that occurred after the last refresh. A stream may contain the latest event but lack the durable identity and historical context needed to interpret it. Combining the layers lets the new signal inherit useful context while the durable profile is maintained through a controlled process.
This does not require every event to rewrite the full customer profile. A system can make streaming data available alongside durable profiles, query the two together, and later incorporate appropriate events into a batch workflow. That distinction prevents a vague real-time claim from hiding different freshness characteristics.
What makes batch and streaming difficult to combine
Time and ordering
Events can arrive late, be duplicated, or appear out of order. Systems need event timestamps, arrival timestamps, deduplication rules, and clear behavior for corrections. Stateful streaming operations such as joins and aggregations also need policies for how long to wait for late data.
Identity
A new event may carry only an email, account ID, device ID, or other partial identifier. The architecture must define how that signal connects to a profile, what happens when the identifier is ambiguous, and whether the action can proceed before a more complete identity process runs.
Data models and business logic
A batch table, streaming event, profile index, and destination may represent the same concept differently. Shared semantics, versioned schemas, and explicit transformation ownership reduce drift between a historical calculation and a time-sensitive decision.
Governance and observability
Fast data still needs consent, access controls, lineage, retention, and auditability. Teams also need to observe ingestion delay, processing failures, index freshness, decision latency, and destination delivery so they can identify where a supposedly real-time experience slowed or failed.
A practical architecture for customer context
Start with a durable identity and profile layer built from the sources required for a reliable customer history. Add streaming only for signals and decisions with a documented freshness need. Keep the match policy, business definitions, permissions, and activation rules consistent across the paths.
For each use case, document the full latency budget: source creation, network delivery, ingestion, processing, profile or index refresh, decisioning, destination delivery, and customer-facing render. Then test failure and recovery behavior, not only the fastest successful request.
How Amperity combines batch and real-time data
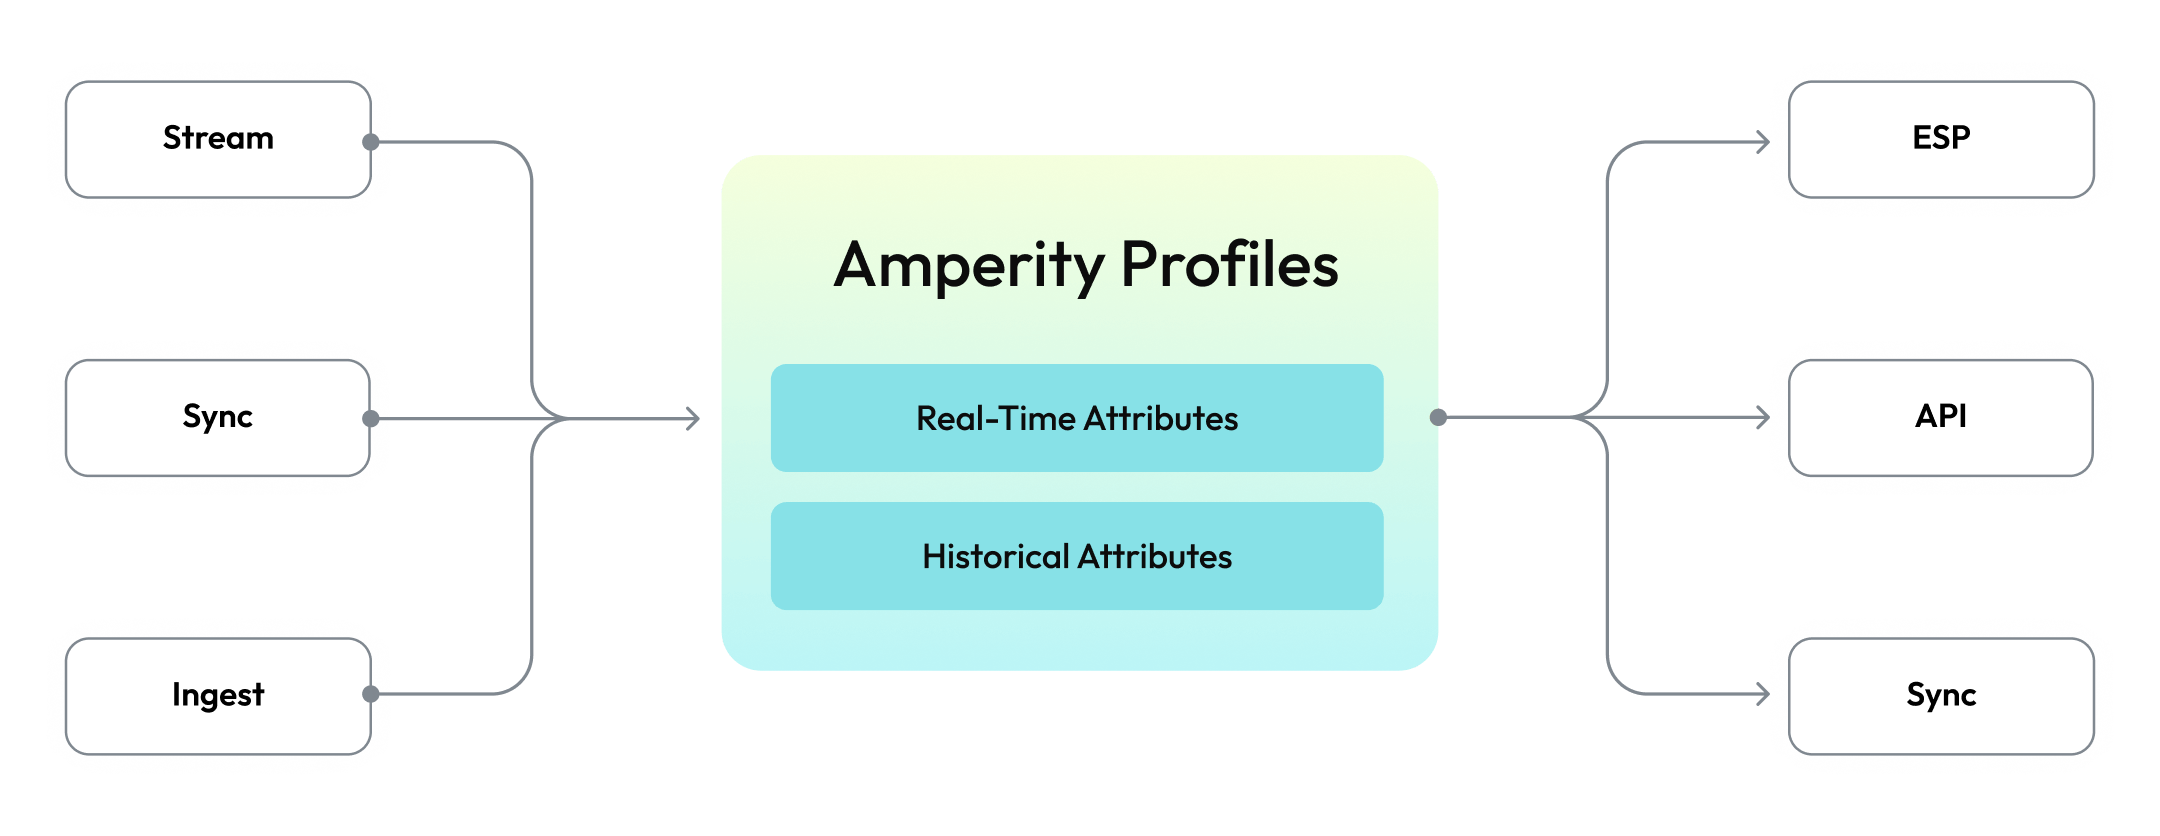
Amperity uses a batch layer to build and maintain durable, complete profiles over longer timeframes. Its real-time tables make streamed data available alongside those profiles for use cases that need updates more often than the typical daily batch. Queries can reference real-time tables and batch-layer tables together.
Current documentation states that streamed data can take up to two minutes to appear in a real-time table and that Profile API data is only as current as the latest index refresh. These details are important when designing and testing a use case. Amperity also provides real-time APIs for streaming events, looking up profiles, and checking segment membership.
Customer use cases for batch plus streaming
Purchase suppression: Use a recent transaction to remove a customer from a promotion or winback audience while preserving the historical profile used to qualify the original audience.
Abandonment: Combine a recent cart or booking event with loyalty, product, consent, and channel context before deciding whether and how to follow up.
Service: Give an authorized agent access to recent transactions alongside durable account and relationship history.
Personalization: Use current behavior or inventory with profile preferences and eligibility rules to select an experience.
Questions to ask before calling a use case real-time
Which source event starts the workflow, and how quickly is it reliably delivered?
Which profile fields, identities, consents, and business rules must be current?
Does the action use the raw event, a real-time table, a profile index, a segment, or a recomputed durable profile?
What is the acceptable end-to-end latency, and what happens when data is late, duplicated, missing, or unavailable?
How will the team measure delivery, customer impact, and incremental business value?
See how Amperity connects durable profiles with time-sensitive signals for customer experiences. Request a demo using your sources, latency budget, and activation path.